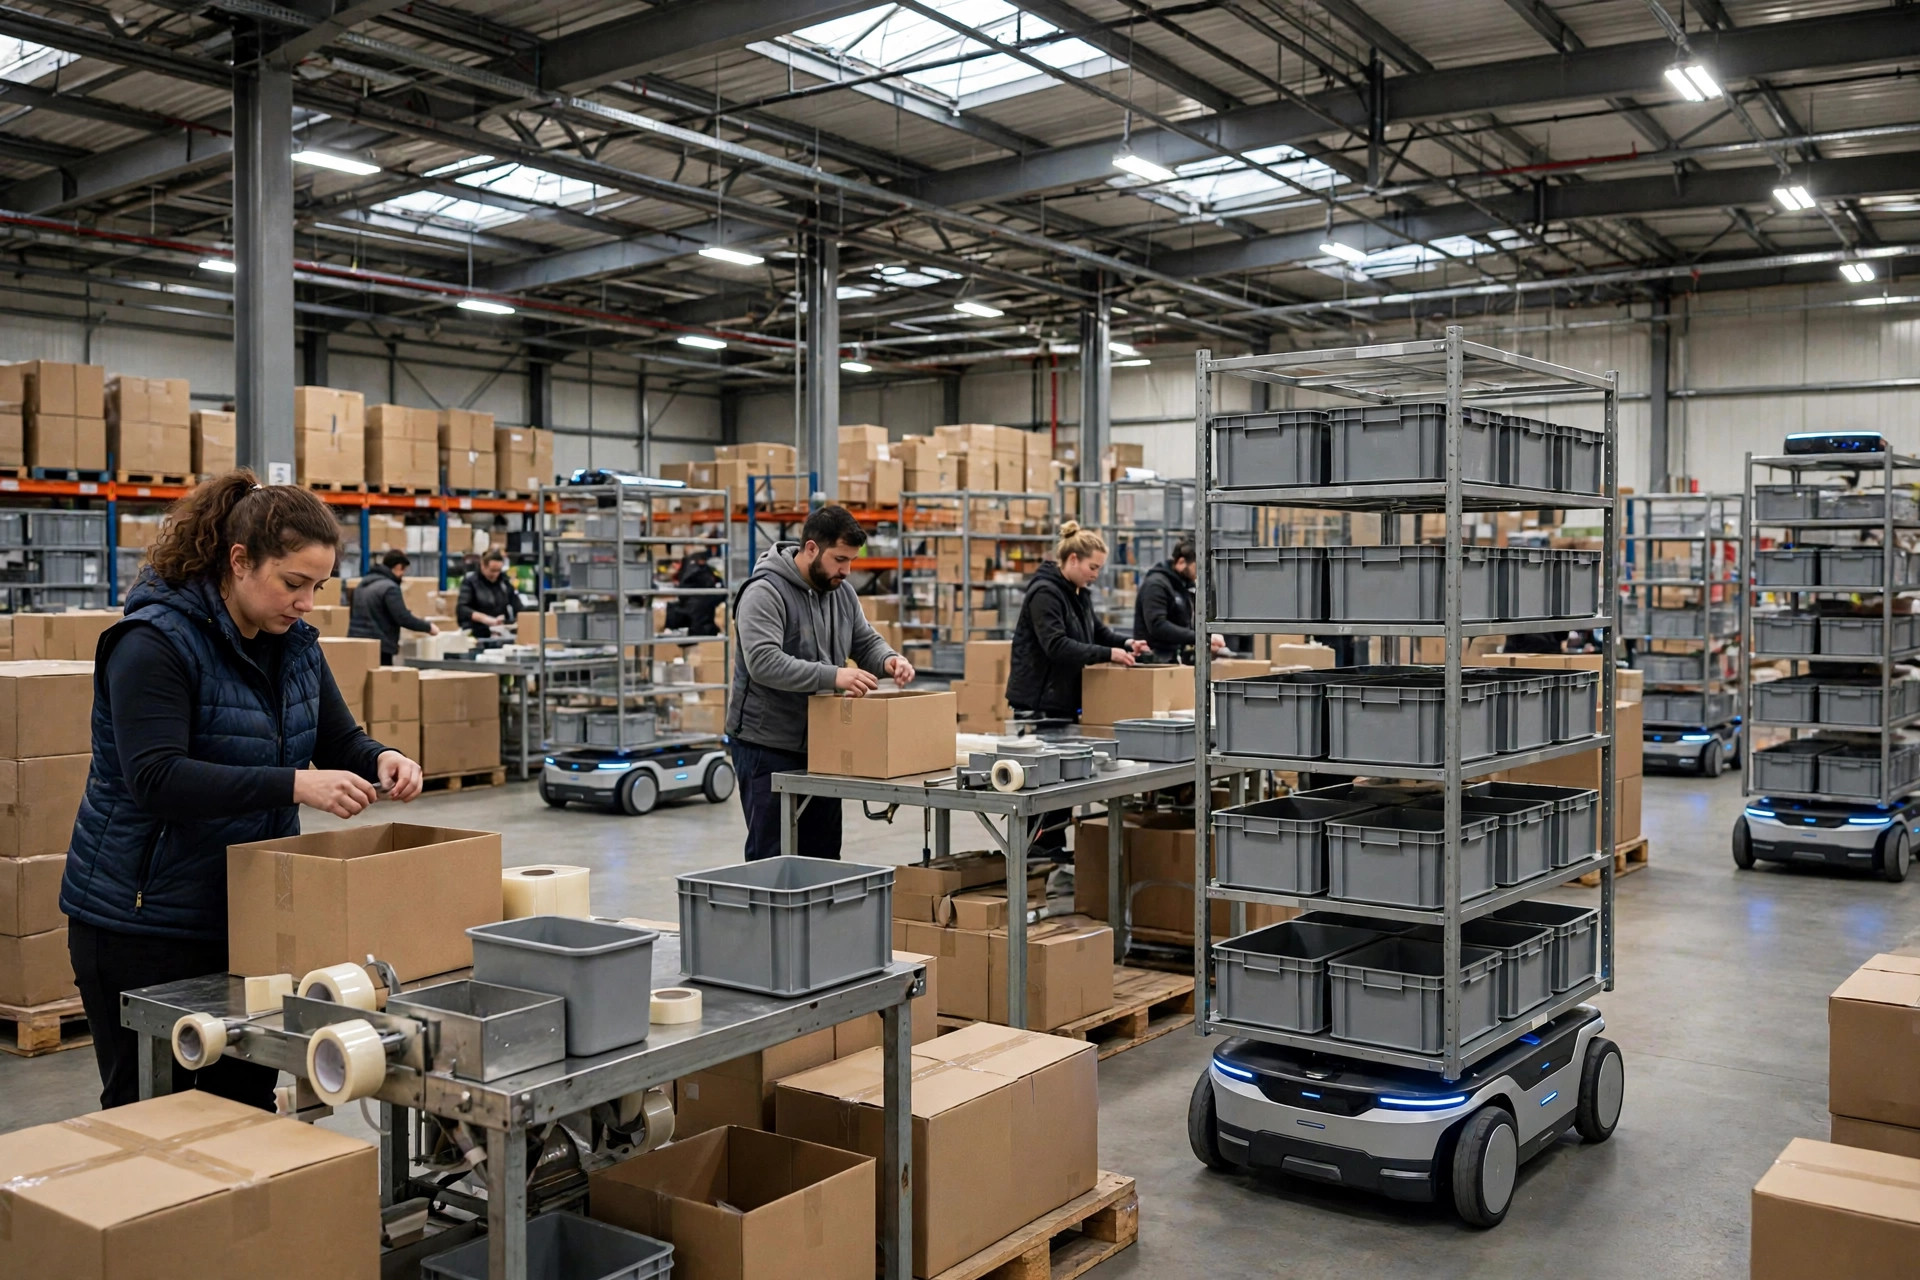
At 12:03 AM the order curve on the monitoring screen shot up like someone lit a fuse. At 12:07 the first 429 came back — the carrier's label API started throttling. By 12:12 the marketplace order-pull API was refusing intermittently too. Out on the floor, a dozen packers stood waiting for shipping labels while the printers sat in an unnerving silence. The IT guy was restarting jobs and typing "don't panic" in the group chat, and everybody could tell he was panicking. That night we survived two hours on handwritten pick sheets, and customer service never stopped ringing the next day.
This isn't a story about badly written software. It's just what peak season does: a system that calls a third-party API tens of thousands of times a day can hit ten-plus times that volume in a single night. Every third-party API has quotas, and when you blow through them, the other side doesn't negotiate — it just says no. Orders stop flowing in, labels stop printing, inventory stops syncing, and your whole operation stalls in front of someone else's servers. This article skips the theory. Here's what you actually do before peak season.
Quotas Nobody Reads Until the Night They Kill You
First: find the quota for every third-party API you call and write the numbers down. Carrier label APIs, marketplace order pulls, ERP inventory syncs, SMS notifications — each throttles differently. Some per minute, some per day, some per account, some per IP. Don't go by memory. Don't "think it's a few hundred a minute." Open the official docs, copy the numbers, note the units.
Second: do the math. Take last year's peak-season spike — or a smaller dress rehearsal like a mid-year sale — multiply by 1.5, and figure out how many calls you'll fire in that midnight hour. Count calls, not orders: a single order can mean three or four API calls (rate lookup, label, tracking push, inventory update), and that multiplier startles most people the first time they compute it. Put the result next to the quota and the gap stares back at you.
Third: request quota increases early. Major platforms and carriers all support pre-peak increases, but it takes a process and a queue — two to three weeks ahead is common sense. Don't just submit a number; attach your math. The engineer reviewing your request responds far better to "peak-hour call volume, duration, breakdown by endpoint" than to "please raise our quota." I learned one the hard way: one year we raised the quota on our primary carrier and forgot the backup lane. On peak night the primary wobbled, traffic failed over, and the backup quota blew instantly. All that preparation, wasted. Cover every account and route you'll actually call — including the backups.
Retries Are Not Supposed to Be Headless Chickens
A quota increase doesn't make you bulletproof. Peak night always brings surprises: the other side's servers wobble, packets drop, an endpoint degrades without warning. How your retry logic is written decides whether you glide through or finish the job of taking them down.
Never write dumb fixed-interval retries. Every failed request retrying every five seconds just hurls the flood back at the wall — the moment the other side catches its breath, you knock it flat again. Use exponential backoff: wait one second, then two, then four, doubling upward, with a little random jitter mixed in. People skip the jitter and they shouldn't: without it, every client retries at the same instant and you get a fresh synchronized flood. With it, the retries scatter.
Backoff needs a ceiling, too: a max retry count and a max total wait, past which you give up and degrade. Infinite retry is the most dangerous pattern there is. I once watched a retry queue grow until it ate the application server's memory — our own system fell over before the vendor's API ever recovered. Lock the retry count and timeouts into configuration during load testing. Editing config on peak night is gambling.
And treat reads and writes differently. Retrying an order pull is cheap. Retrying a label print or an inventory decrement is not — so ask about idempotency before you retry a write. If the same order prints twice, does the carrier dedupe it or do you get two labels? Are you billed twice? Nobody asks these questions on a calm Tuesday; peak night will teach the lesson for you. Idempotency keys belong on every write call that touches money or physical goods. Don't discover duplicates at reconciliation.
When It Really Breaks, Degrade With Dignity
Backoff and queues buy time. Degradation admits reality: their API is down and your warehouse cannot stop. The degradation plan gets written and rehearsed before peak season — not invented at 12:12 AM.
The workhorse move is "take the order now, sync later." Can't pull marketplace orders? Produce from locally cached orders, print labels on the backup carrier, and backfill the data when the API recovers. Inventory sync jammed? Keep shipping, log the discrepancies, reconcile by hand afterward. One principle: protect the lifeline — freight going out the door. Anything non-real-time can lag.
Degradation should have tiers. Light: kill non-critical calls — switch SMS notifications to a post-peak batch and free the quota for label printing, the call that keeps you alive. Medium: fail over to the backup lane even if it's slower or pricier. Heavy: go manual — blank labels filled in by hand, spreadsheet-driven picks. It sounds primitive, but when you're there, a primitive plan beats staring at a dead screen. Each tier's trigger and steps fit on one printed page taped to the on-call desk. Nobody does clear thinking at midnight on peak night.
Underneath it all sits a queue. Every call that normally hits a third party directly should go through a local queue first during peak, consumed at a steady rate under the quota. Set alert watermarks on queue depth: past the line, light degradation kicks in automatically. Build this in normal times, not the week before peak — the queue's own stability and monitoring need time to prove themselves.
Two Weeks Out, Walk This List
Here's the pre-peak checklist, ready to tick off: every third-party quota copied down; peak call volume computed; increase requests filed, backup lanes included; retry policy live — exponential backoff with jitter and a hard ceiling; write-call idempotency confirmed; the three degradation tiers written and rehearsed once; the smoothing queue live with alert watermarks set; the on-call roster and escalation path posted.
One thing you can do tomorrow: open your system's third-party integration config, find each API's quota limit, and build the table. That one table is the difference between sleeping the night before peak season and living through another night like the one I opened with.