
Bottom line up front: AI POC acceptance metrics must be negotiated and written into the contract before anyone signs — negotiating after the signature hands the vendor all the cards. Three things to lock down: at least six metrics — precision, recall, false-positive rate, miss rate, latency, stability — each defined by four elements (definition, sample, measurement, threshold); and staged payments, each gate releasing the next one. I have watched this exact failure happen three times, and every time the contract held a single line: "accuracy shall be no less than 95%."
Why POCs keep dying at go-live
The numbers are brutal. S&P Global's 2025 survey: 42% of companies scrapped most AI initiatives, double the 17% a year earlier, and the average organization killed 46% of its AI proofs of concept before production. MIT's Project NANDA: 95% of enterprise generative AI pilots produced no measurable P&L effect. Most had "successful" POCs — beautiful demos, impressive metrics. They died between the demo and deployment.
Three reasons. First, the POC data was cherry-picked: 500 perfectly staged photos, nothing like the crushed cartons and wrinkled labels on your real conveyor. Second, the POC ran in a lab with engineers tuning live beside the machine — production offers no such luxury. Third, the contract metrics were mush: "95% accuracy" with no definition of "correct," no counter, no sample is an IOU written on air.
War story: a 97% POC that went live at 81%
May 2025, Chicago. A 3PL handling oversized e-commerce goods — 120,000 square feet, 20,000 units a day. The owner wanted machine vision on the conveyor to replace four inspectors. The vendor's POC was gorgeous: 500 photos, 97% accuracy. The contract had one line: "system recognition accuracy shall be no less than 95%." The owner signed happily.
Week one of go-live, it blew up. Full conveyor speed, skylight glare, damaged parcels in every imaginable shape — critical-field accuracy dropped to 81%, false positives hit 14%, each costing about two minutes of line-stop review. The operators switched the system off — the manual process was faster. Then came three months of finger-pointing over what "accuracy" even meant; the contract had never defined it.
The rescue took one move: a supplementary agreement with five metrics, each carrying the four elements. The vendor tuned free of charge for two more months: false positives fell to 4.5%, critical-field precision hit 98% and recall 96%, stable across two weeks of production data. Only then did it pass.
The control group: a project that wrote it all down first, and passed the first time
February 2026, a pharmaceutical 3PL's temperature-controlled warehouse in California: AI-assisted cycle counting with drones reading high-bay locations. Three weeks before signing, I helped the customer write the acceptance metrics as a contract appendix — a golden sample of 300 locations, drawn at random by the customer, heavy on high bays, occluded slots, and wrinkled labels; acceptance measured over two weeks of live cycle counts against three numbers: count variance rate, false-positive rate, seconds per location. The POC passed on the first attempt, the pilot hit its targets in two weeks — zero arguments. The lesson: acceptance metrics are not summarized after the POC; they are negotiated before the signature.
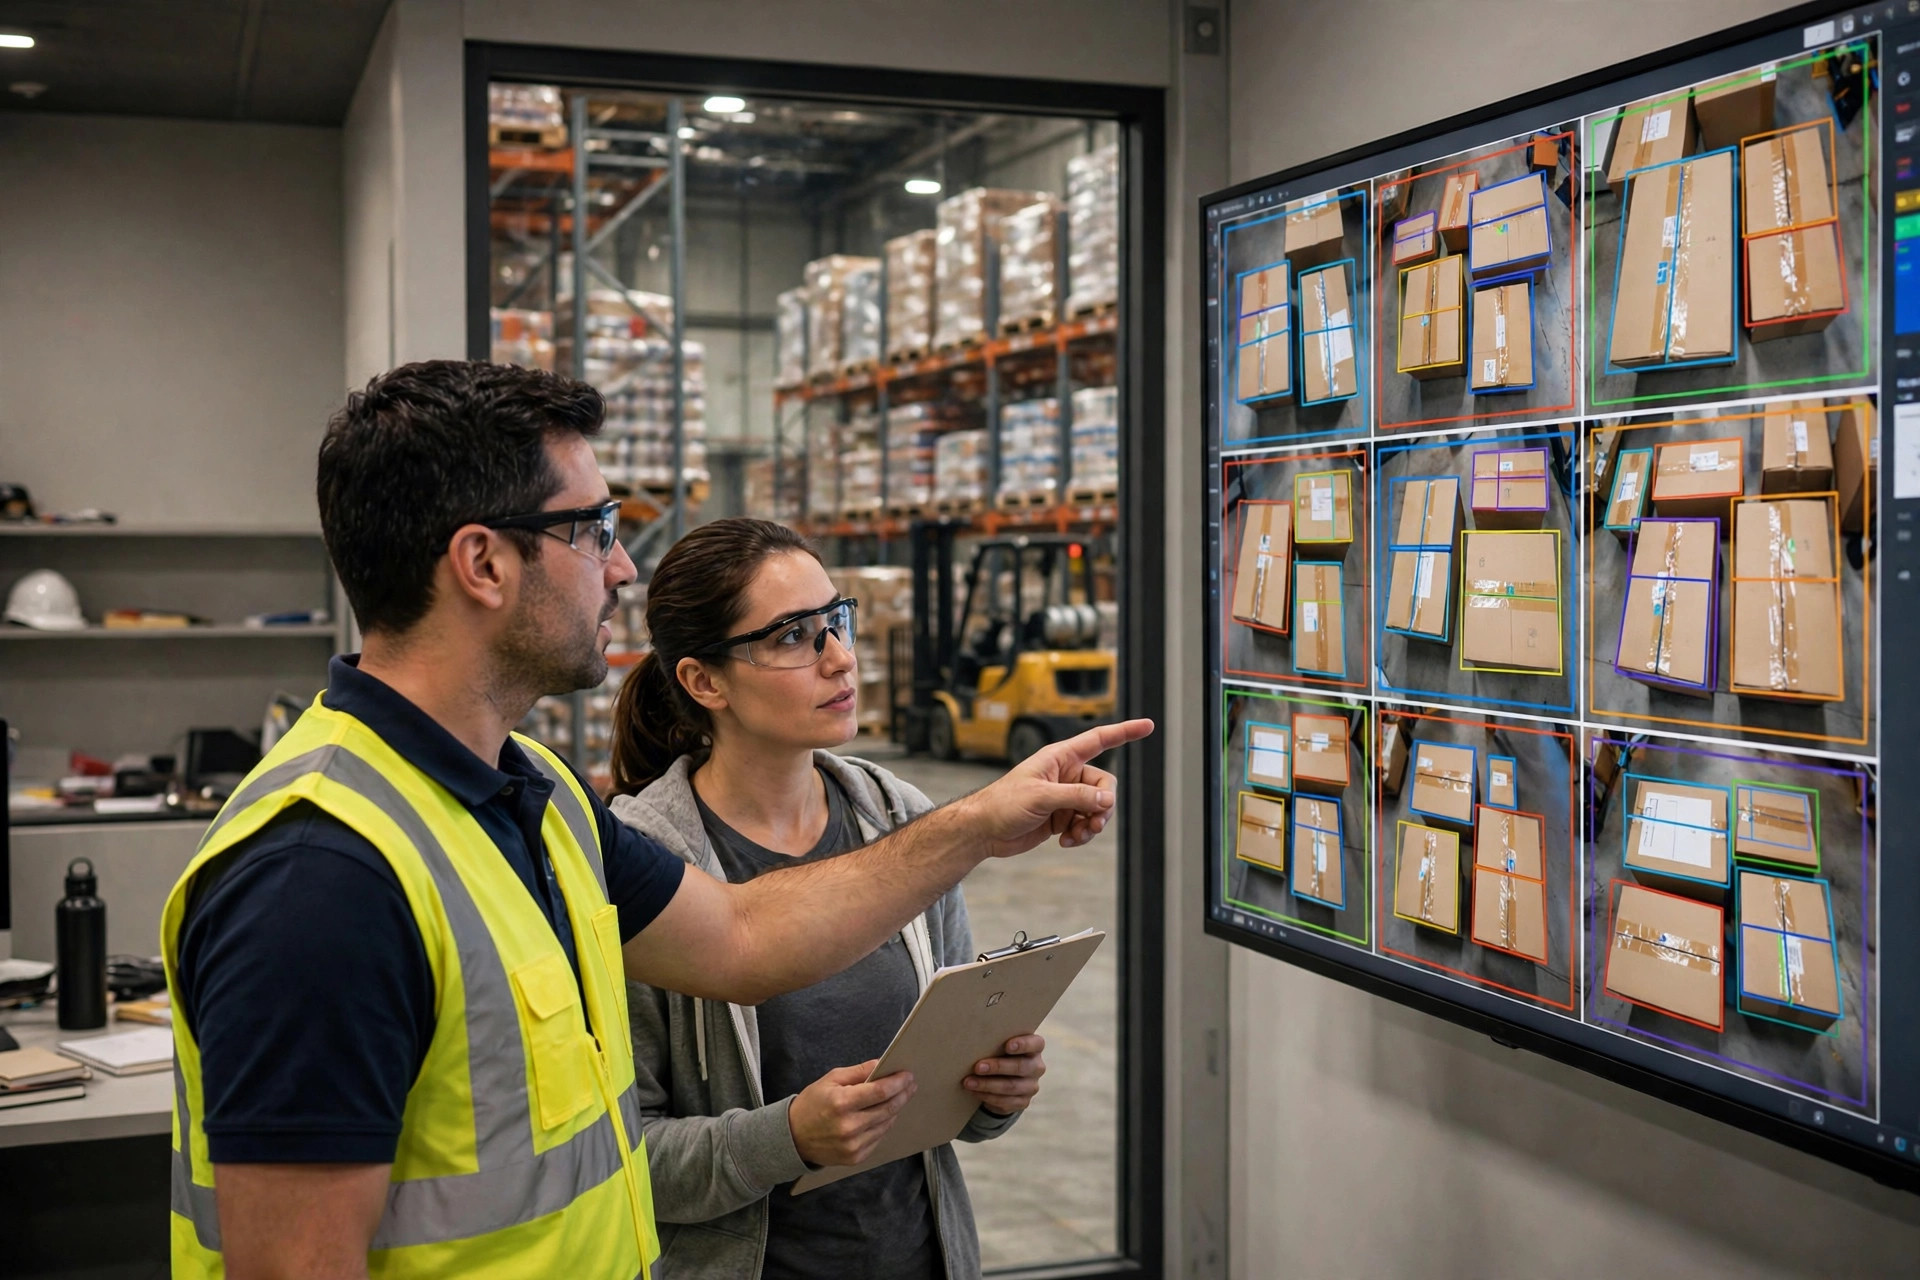
The six metrics, step by step
Each of the six needs four elements: definition, sample (what data, drawn by whom), measurement method (whose count wins), and threshold. A metric missing any one of the four is decoration.
Metric 1: precision and recall, written separately. "95% accuracy" is the most dangerous sentence in an AI contract. Precision is the share of the system's flags that are correct; recall the share of real cases it caught. Write only "accuracy" and the vendor optimizes the easier one. Contract language: critical-field precision ≥ 98%, recall ≥ 96%; the gate clears only when both pass.
Metric 2: false-positive rate. The number that decides whether the project lives or dies — 14% versus 4.5% is not a 10-point gap, it is several headcount (math below). Set the threshold backwards from your staffing: how many exceptions can one shift absorb?
Metric 3: a floor on the miss rate — a red line for safety and money fields. An undetected damaged parcel, a missed temperature excursion — one incident costs more than a hundred false positives. These fields get their own recall red line; one breach triggers the review workflow.
Metric 4: latency, stated as P95 — never the average. An average of 200 milliseconds sounds lovely until the P95 is 2 seconds, and the conveyor does not wait for your slowest 5%. Contract language: at production takt, P95 latency ≤ X milliseconds, with X derived from your line speed.
Metric 5: throughput against the human baseline. AI is not here to perform; it is here to work. Units per hour and cost per unit sit beside the manual baseline — measured before the POC, written into the contract.
Metric 6: stability — passing across N consecutive production days. On POC day the vendor's engineers camp on site and everything looks great. Demand two weeks of production data, scored per day: 12 of 14 clearing the bar. A single passing day does not count.
The math: what 14% vs. 4.5% false positives costs in headcount
Chicago's numbers — 20,000 units a day, about two minutes per false-positive review:
| 14% false positives (early go-live) | 4.5% false positives (after tuning) | |
|---|---|---|
| Units entering the review queue daily | 2,800 | 900 |
| Daily review hours | about 93 | about 30 |
| Full-time equivalents (8-hour shifts) | about 11–12 | about 4 |
| vs. the original 4 inspectors | 7–8 extra hires | Roughly break-even |
See the point? A system at 14% false positives costs more than the manual process it replaced: four inspectors out, eleven reviewers in. That is why the false-positive rate belongs in the contract: it decides whether the project saves money or burns it.
Three contract clauses the metrics need
Without these three, the metrics are unenforceable.
First, the customer owns the acceptance sample. The golden dataset is drawn at random by the customer, tested blind by the vendor, and must include dirty data and the long tail: wrinkled labels, reflective tape, crushed parcels, occluded slots. The vendor picking its own POC samples is fair game; acceptance runs on the customer's.
Second, stage the payments. POC acceptance, pilot acceptance, stable production — three gates, each releasing the next payment, and the final holdback must be large enough to keep the vendor tuning.
Third, define the miss path: a free tuning period plus an exit clause. Window length, round count, and the still-missing outcome — refund ratios, data ownership, de-installation costs — all in writing. An exit clause is not a curse on the project; it is a dignified stop-loss for both sides.
The usual crash sites — I have watched this happen three times
Crash 1: the contract says only "accuracy." The vendor drives the easy metric to 99%, the hard one sits at 80%, and the blended number still looks fine.
Crash 2: the vendor picks the acceptance sample. The 500 staged POC photos were beautiful; production data was not.
Crash 3: a single passing day counts as acceptance. On POC day the vendor's engineers were on site, tweaking parameters live. That is an open-book exam, not a pass.
Crash 4: no measurement method in writing. In the Chicago project, 80% of the three months of arguing was spent on "how do we even calculate this."
A counterintuitive take
Tighter metrics are not better metrics. I have seen a customer set precision at 99.5%. The vendor overfitted to the customer's sample during the POC — tuning relentlessly against those exact images. Acceptance passed on the first try; go-live failed anyway. The model had memorized the sample, not the business. A reasonable bar plus a clear exit clause beats a draconian penalty every time. Acceptance metrics filter "can this work" — they are not a strictness contest. Set a line the vendor can clear with a stretch, pair it with a clean breakup mechanism.
The go-live-night checklist
Five questions before the pen lands:
- For each of the six metrics, are all four elements (definition, sample, measurement method, threshold) written down?
- Did the customer draw the golden sample — dirty data and long tail included?
- Are payments staged, with a holdback big enough to keep the vendor tuning?
- Is the miss path written down, and does both sides accept the exit clause?
- In a dispute, whose measurement counts — is that written?
If you cannot answer one of the five, do not sign. Tape this checklist to the contract's last page, photograph the signed page, post it in the project chat. Across 30-plus go-lives, that is the one ritual never proven unnecessary.
By Lin Xiao, WMS Implementation Consultant





