Here's the bottom line: warehouse execution system exception management is not about preventing failures — it's about knowing exactly what the execution layer should do in the first ten minutes after one happens. I've seen this exact failure three times, and all three followed the same script: a carton jammed on a sorter, the task sat "in progress" in the WES forever, and nobody knew it was dead until the wave blew past its cutoff and a customer called to complain. A mature exception setup does exactly three things: a timeout threshold for every failure type, a recovery action for every timeout, and a manual-takeover path for every recovery action. Get those three into your go-live eve checklist, and the next stuck task, dropped connection, or dead device gets handled by the system first — buying your people time to reach the floor.
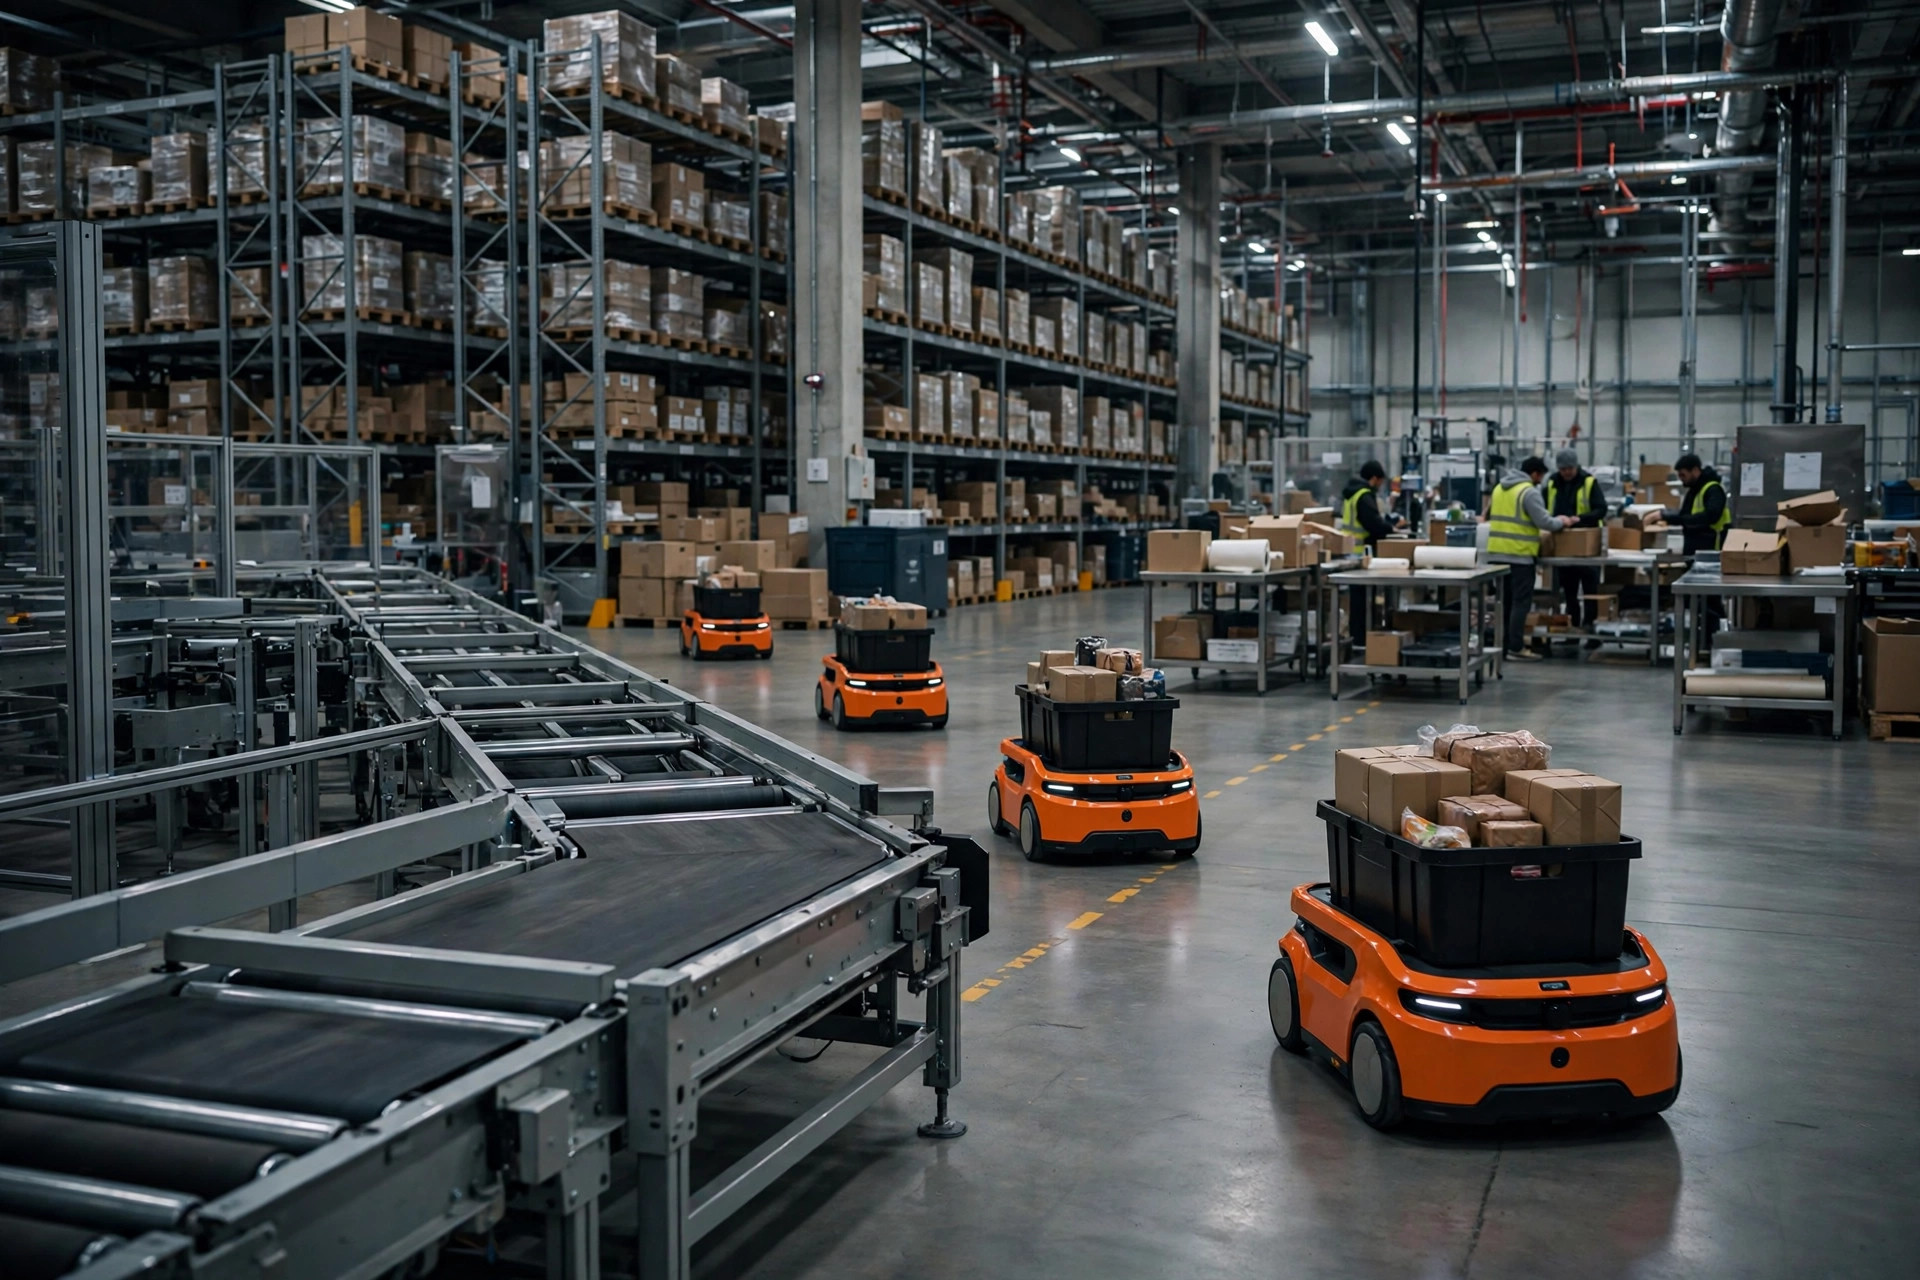
Get the division of labor straight first, because this is where most projects go wrong. The WMS decides what to do — waves, task assignment. The WCS tells equipment how to move — motors, grippers, diverters. The WES sits between them and owns where things stand: which step each task is on, where it's stuck, and what happens next. Too many projects treat the WES as a relay — WMS instructions forwarded to the WCS verbatim, statuses passed back verbatim, zero exception logic in between. That makes the execution layer brain-dead. Fine on a quiet Tuesday; a dumpster fire the moment anything breaks. Across 30+ go-lives, execution-layer meltdowns trace back to this gap more often than anything else.
Warehouse Execution System Exception Management Starts With Three Buckets
Classify before you act. Get the bucket wrong and everything downstream is wrong. Execution-layer failures come in exactly three flavors:
- Stuck tasks. The task went out; no confirmation came back. Either genuinely stuck (a carton tipped and wedged in a chute) or phantom-stuck (the goods arrived, the confirmation got lost on the way).
- Dropped connections. The link between WES and WCS/equipment died. Heartbeat gone, WES flying blind.
- Dead equipment. The device reported a fault itself — motor overload, a scanner that can't read, an AMR that ran out of battery mid-aisle.
Each bucket needs different recovery logic. Stuck tasks need verify-then-act. Dropped connections need reconcile-before-you-touch-anything. Dead equipment needs quarantine-first. Mix them together and you're manufacturing disasters.
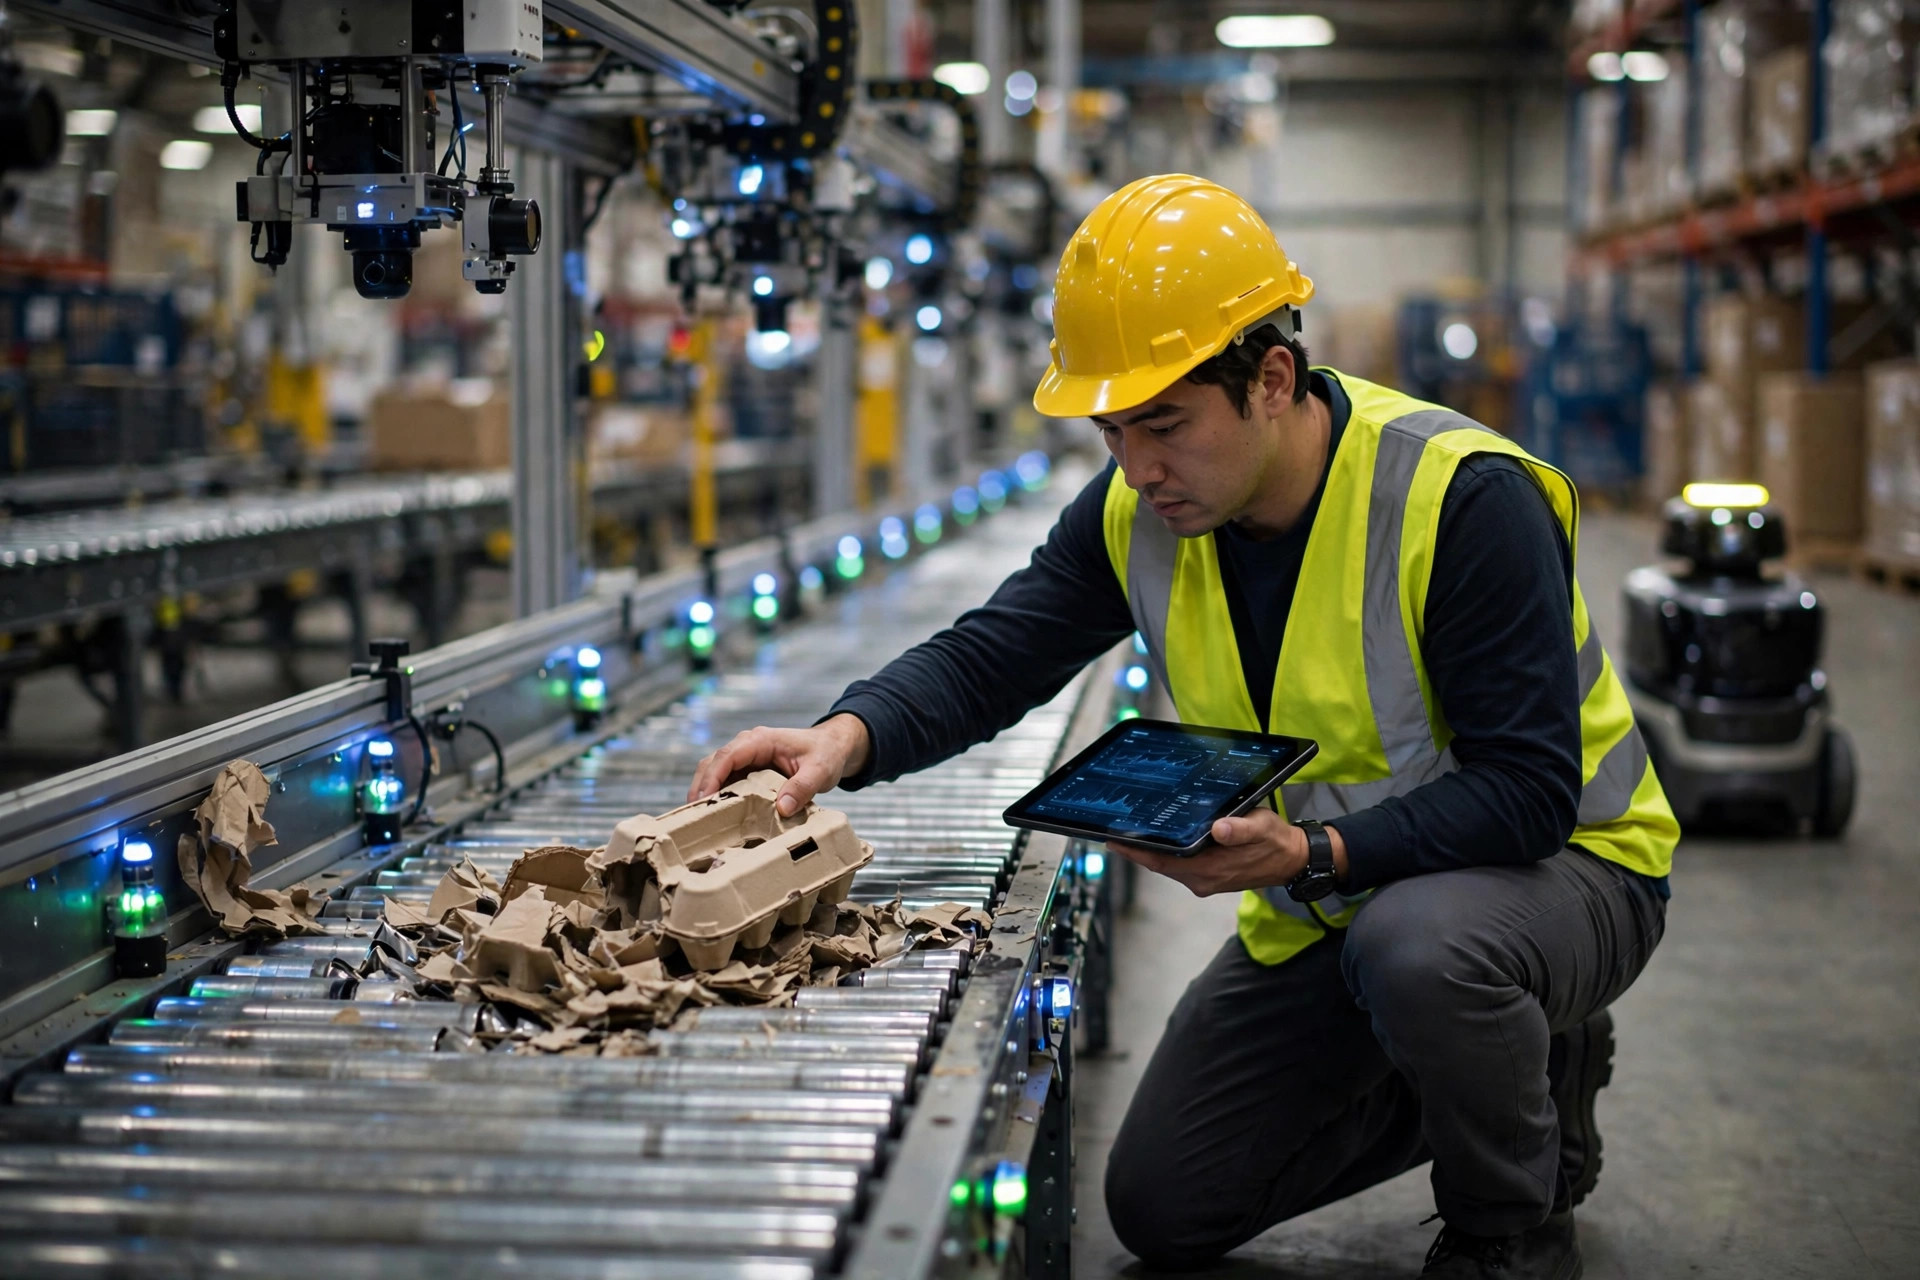
May 2024, a 3PL in Ontario, California — roughly 120,000 square feet, about 18,000 orders a day. A carton tipped on the cross-belt sorter and wedged a chute. In the WES, that task stayed "in progress" for three solid hours, because nobody had configured a task timeout at go-live. Four hundred-plus orders in the same wave sat behind it until a night-shift supervisor happened to walk past and see it. The customer's own accounting: picking and packing basically stood still for those three hours. We fixed it overnight with three things: a 10-minute task-level timeout, a 5-minute equipment-state timeout, and a wave cutoff alert. Three days later the same chute jammed again. This time the system rerouted the task to manual handling and routed the wave around it in eight minutes. Same jam. Three hours versus eight minutes. The difference was three lines of configuration.
Stuck Tasks: Verify First, Then Pick Your Recovery Move
Stuck tasks are the most common exception on the floor. Three steps, none optional.
Step 1 — Locate. Open the WES task monitor or exception board, sort by stuck duration, and the red rows at the top are your suspects. Write down three values: task ID, which device, which step. Target: located within one minute. If you can't, your board is broken — send it back.
Step 2 — Verify: real or phantom? This is the step that matters most and the one most teams botch. Real versus phantom decides which road you take, and that is the heart of warehouse execution system exception management: verify before you act. Walk the floor or check the WCS device logs. Never hit "force complete" before you've verified — I've watched three customers click that button, and two of them created mis-ships. Phantom stuck has a classic look: the goods arrived, the confirmation died in transit. Right before Singles' Day 2023, a beauty e-commerce warehouse in East China had dozens of AMRs queuing "dead" at the charging zone — 200+ unfinished tasks piled up in the WES. On the floor, everything had been delivered. The warehouse WiFi was dropping packets during roaming, and confirmations never made it back. We reconciled against actual WCS positions and bulk-confirmed. Not a single unit was lost — but nobody on that team slept that night.
Step 3 — Pick the recovery move. Three options, tried in order:
| Recovery move | When to use it | Recovery time | Risk |
|---|---|---|---|
| Retry the task | Phantom stuck or one-off jitter; equipment itself is healthy | Minutes | Low — but cap the attempts |
| Reroute | Genuinely blocked but avoidable (different chute, alternate conveyor branch) | 5–15 minutes | Medium — confirm the new path is actually clear |
| Manual takeover | Equipment fault, can't verify, or retry cap hit | Depends on response time | Low — but it drags the wave |
The decision rule fits in one sentence: check whether the equipment can still move; if yes, retry or reroute; if no, hand it to a human. Don't get it backwards.
Here's the counterintuitive part: more automation in recovery is not better. I worked with a warehouse whose WES retried without a cap. A conveyor motor had already thrown an overload alarm, and the system kept re-sending the task — 47 retries later, the motor burned out. A minor jam became a major repair. One hard rule: cap automatic retries at three, then circuit-break to manual. Automation buys you time; it doesn't replace judgment. When equipment is genuinely broken, the harder the system "tries," the faster things die.
Dropped Connections and Dead Equipment: The Other Half of Exception Management
Connection dropped? Don't touch anything until you've reconciled. When the WES–WCS heartbeat dies (set the heartbeat timeout from the equipment vendor's latest published specs — don't guess), the WES must do three things: first, mark every in-flight task "pending verification" — no retries, no cancellations, because retrying during an outage is the most dangerous move you can make; duplicate commands on reconnect will confuse the equipment. Second, wait for the heartbeat to return. Third, reconcile WES task states against actual WCS equipment states line by line, with a human confirming every mismatch. Releasing tasks before reconciliation is complete is driving blindfolded.
Equipment faulted? Quarantine first, recover second. The moment a device reports a fault, the WES should automatically pull it from the available-equipment pool and reroute in-flight tasks around it. When maintenance says it's fixed, a human must confirm it back into the pool — never let the system auto-readmit it. Why? Because "fixed" is a human judgment, not a sensor reading. I've seen a warehouse with auto-readmit put a sick device back on the line; it died again thirty minutes later, and the same wave got burned twice by the same machine.
The Go-Live Eve Checklist: Seven Boxes or No Go-Live
- Timeout thresholds for all three failure types are in the configuration table, each with a documented basis (vendor spec or measured data). No blanks.
- The exception board works: stuck tasks pinned red at the top, sorted by stuck duration, locatable within one minute.
- Automatic retries capped at three, circuit-breaking to manual past the cap — in code, not as a verbal agreement.
- The dropped-connection reconciliation flow has an owner, and the on-call list is on the wall — reachable at 3 a.m.
- The "force complete" button is disabled, or at minimum gated behind two-step confirmation with an audit trail. Exceptions get "manual takeover" only.
- Wave cutoff alerts: a wave blowing past its cutoff (set your own — say, 15 minutes) escalates automatically. Don't wait for the customer's phone call.
- Run a pull-the-cable drill before go-live: unplug the network and watch whether the WES survives the first wave on its own. If it can't, don't go live.
Every line on that list is a 3 a.m. someone already lived through. A checklist isn't bureaucracy — it's trading someone else's all-nighter for your peace of mind.
One thing you can do tomorrow: tonight, check whether your WES even has a task timeout configured. If it doesn't, add one — a conservative value beats no value every time. And ask yourself one honest question: the last time a task got stuck in your warehouse, how long did it take the system to tell you? If the answer is "a person found it," this article was written for you.
By Lin Xiao, WMS Implementation Consultant